✅ Your Agent Read the Skill. Did the Check Run?
📅 Wednesday, Nov 4, 2026
⏰ 6:30 PM
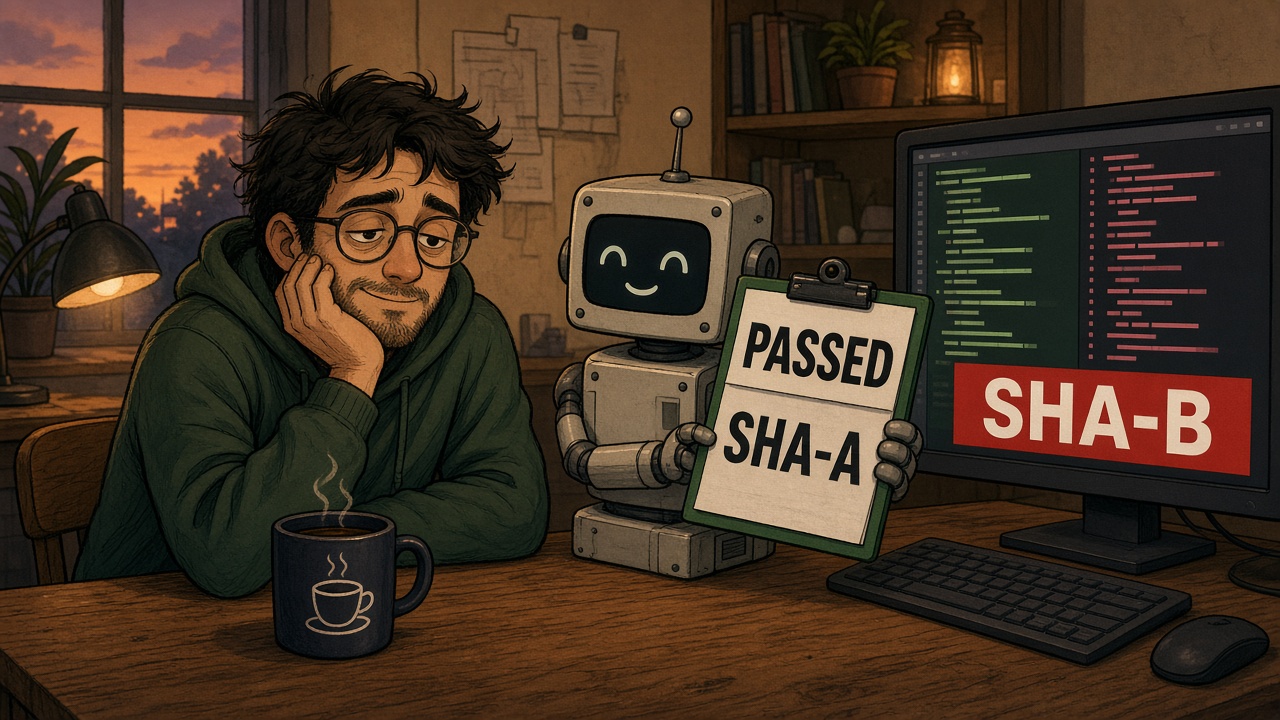
A skill is worth using only while you watch the model invoke it and follow it; hand that step to a factory and the miss ships, tokens spent either way. The coding agent says the pull request is ready. It loaded the team’s review skill, ran the review, and pushed a small fix. The review it called complete belongs to the previous commit. I can catch that while I’m sitting there: I look at the SHA and ask what actually ran, then send the agent back over the new diff. Put the same workflow on a webhook, hand it a service identity, and let it run at two in the morning.
That’s the line I draw between an agent skill and an application harness. A skill gives the agent the team’s procedure. The harness is the code and config around the agent that decides which operations are allowed, which steps are mandatory, and what evidence has to exist before the work moves. I made the unattended case in The Jig .
The skill works while I’m watching
A good review skill tells the agent how my team handles a database migration and where the integration tests live. Mine include a script that pulls facts the model would otherwise guess. I keep that guidance from session to session.
It is worth having because I can see two things the model’s own report leaves out: whether it invoked the skill, and whether it followed the instructions. Following them is non-deterministic. The model can follow the instruction or skip it, and it will still tell me the skill was followed. I watch that miss happen. A check that fails the work catches it, and so does a prompt that sends the agent back to the instruction it dropped. Either correction is enough while someone is in the chair. Without one, the person in the chair is the only verifier, and someone has to sit through the run.
Anthropic’s write-up of Agent Skills
matches how I use them at the keyboard. A skill is a directory: instructions in SKILL.md, plus the scripts and files those instructions name. At startup the agent sees each skill’s name and description. It reads the body only when it decides the skill fits, and it can run a bundled script without pulling the script into context (the right tool for a job that should come out the same way every time). Anthropic is clear that the model runs that code at its discretion.
I can live with that discretion while I am the one who notices the script never started. I won’t ask a factory to notice. A dark factory that does not stop producing, or a software factory that automates a step the model can still talk its way past, turns the miss out faster than anyone can read it. The tokens are spent on the run the model took, followed or not. The waste is visible from the chair. I will not leave that control on the line.
The domain factory is yours. The review cell is not.
The engineer who is left is the domain expert, building the jigs for a factory that knows one domain. I named the jig in The Jig : the path and the test for one class of work, clamped down so a person doesn’t have to watch every move. I argued in The Software Factory Was Already Here that you automate a station only after that check is already real. The factory you are willing to leave running is the one you built for the domain, out of those jigs, plus the harness you wear while you are still in the loop. A few of the smaller factories inside it are yours too.
A firm whose product is a legal review, arriving with its documents and a briefing a lawyer can use, doesn’t want a general coding line. It wants a factory for that practice. The person who knows that practice is the one who can say the spec for that briefing is the right spec. The jigs that hold a draft to it are what that person builds. So is the harness, for as long as a person is still sending the work back. Even the research that figures out how to build the factory is a smaller line, with its own jigs and its own harness, and the spec on that line is still theirs to get right.
Then there is a part you can stop building. It starts only after the domain and the design are settled and the code exists. Find the bugs, and check that the change does what the spec said and nothing the spec did not ask for. The same pass asks whether the change stays cheap to run and cheap to change inside the architecture you already have. That pass is the same in a law firm and in a payments company. Manufacturing already named the small factory that does one family of work, including information work: a workcell. Schonberger describes Skinner’s focused factory (Harvard Business Review, May 1974) as the large form of that idea, a plant made of workcells, and he quotes Hyer and Wemmerlöv (2002) on a cell as dedicated resources for a family of products or information deliverables. A code-review workcell will give you that pass. It won’t tell you the spec was the right one, and it won’t tell you the finished work is what the practice needed. I’d take the workcell. I wouldn’t call it the factory.
Loading the skill isn’t the check
SkillsBench measured curated skills against the same tasks with no skills. On 87 tasks and 18 model-harness setups, the average pass rate rose from 33.9% to 50.5%, a gain of 16.6 percentage points. Software engineering was 16 of those tasks, and the gain there was 11.6 points (37.6% to 49.2%), smaller than every domain except Mathematics & OR. Tasks paired with one skill gained 18.0 points; the group with two to three skills gained 19.0; four or more gained 10.1. Thirteen of the 87 tasks scored worse once the skills were attached.
SWE-Skills-Bench
is the study I’d read before installing a public skill. They pinned 98 public software-engineering skills to 98 repositories, wrote ten requirements from each skill, and ran every requirement with the skill and without it: 3,920 paired runs, four agent-model setups (Codex on GPT-5.4-mini and on Kimi-K2.6; Claude Code on Kimi-K2.6 and on Haiku 4.5). Ninety-two of the 98 skills had no statistically significant effect. The average pass ratio moved from 76.6% to 76.9%. Four skills helped, and the best of them gained 17.7 points by getting the agent to use the spf13/viper library the tests expected. Without that skill, half the runs wrote a config loader of their own. Two skills hurt. asyncio-patterns cut the pass ratio by 17.0 points; the traces show its templates overriding the task, including where the files had to go.
Dong, Gao, and colleagues (Dong’s work was an internship at Microsoft Research) took failures on those two benchmarks and blamed a specific loaded skill. The comparison was a paired run with no skill, or with a different skill that solved the task. They kept 307 cases: 125 where the skilled run failed and the reference passed, and 182 where both passed but the skilled run spent more tokens and more time, with at least one of those at least doubled. Of the 125 functional failures, 86 came from a skill that looked relevant and still led the agent to implement a required behavior wrong or leave it out.
Two limits, and then I’ll stop hedging. These are benchmark tasks with a checker that returns pass or fail, not a pull request in a repo I maintain. SWE-Skills-Bench wrote its ten requirements from the skill text, so a skill can look idle there and still matter on work it wasn’t built to trigger; their “no effect” label means a sign test on those ten didn’t reach p < 0.05, which isn’t a measured delta of zero (the paper’s protocol ). I won’t treat “the skill was loaded” as proof the check ran on this SHA.
The script still waits for a caller
A script inside the skill will apply the same rules to the same input every time it actually runs. Something still has to start it on the revision under review and stop the workflow when it exits nonzero. OpenAI’s Skills guide
says who makes that call. Once a skill is mounted, “the model can decide when to use it.” Telling the model to use a named skill is what they suggest when you want tighter behavior, and they still call that an instruction: the model chooses whether to invoke the skill from its name and description, then reads SKILL.md if it does. I measured the same split as rules in the model versus rules in code
.
Bind the result to the SHA
For a pull request, I want the harness to resolve the revision and run the required checks. The gate should take a result only from the review service I configured, for that SHA, under the policy version that applies. If the review service times out, retry inside a limit I set and leave the merge blocked.
A new commit voids that result.
GitHub will store that fact when branch protection is on and the exceptions are closed. A commit status is posted to one SHA , so the green mark stays on the commit the agent reviewed. Dismissing stale approvals drops a human review when a later push changes the diff GitHub saved at approval time. A required check can be limited to one GitHub App, and a status from anyone else won’t clear the merge; anyone with write access can post one . Admins skip these rules unless you enable “Do not allow bypassing the above settings,” so the agent has to run as a user the rule covers.
The model keeps the work it’s actually good at. It can read a diff for a race and say why a reviewer should care. When policy says a rule has to run on every change that meets a test I wrote down, the harness decides the rule applies and demands a result. Clearing the gate tells me the process ran, and whose result came back. Whether I trust the change still depends on the tests, and on whether that review was any good.
Encode the rule where the check can fail
OpenAI’s harness write-up
is the example I keep, minus one choice. They describe an internal product with no hand-written code. A short AGENTS.md is a map into docs that live in the repo, and custom linters plus structural tests hold the architecture. Structured logging is one rule they check statically. Because the lints are theirs, the error text tells the agent how to fix the violation. They also left blocking merge gates minimal (at their throughput, they argue, a follow-up fix was cheap and waiting wasn’t).
I’m keeping the lint.
Three tests before it runs alone
When the workflow leaves my session and runs as a service, I want three tests before I’ll leave it on overnight. Skip the skill and confirm the required checks still run. Time the review service out and confirm the merge stays blocked. Push another commit after the review and confirm the old result can’t clear the gate.
The stamp says passed.
The sheet under it is SHA-A. The screen is SHA-B.